How transformers think
One prompt, “The cat sat”, through the whole model: tokens, embeddings, the attention matrix, the feed-forward layer, and the probability over the next word.
 Index Ai Academy
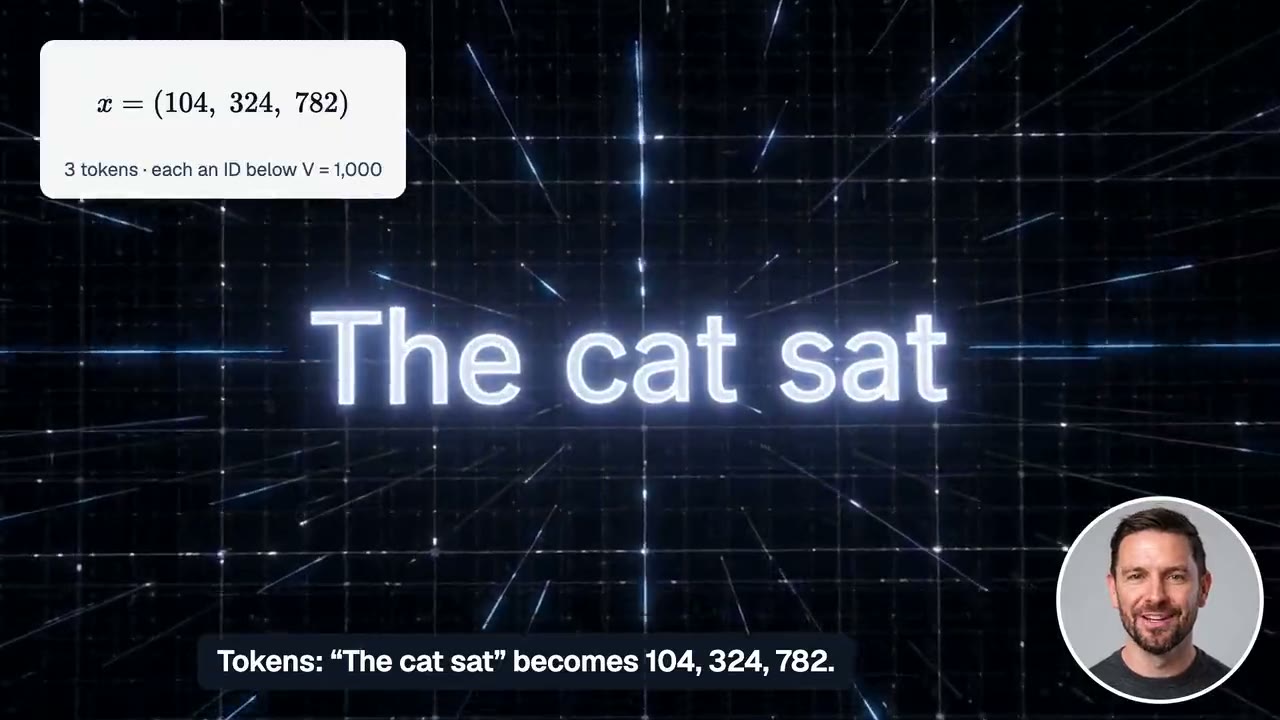
“The cat sat” is cut into three tokens and looked up as 104, 324 and 782: a tensor of shape (3,) with T = 3 and V = 1,000.
A model never reads letters: a tokenizer cuts 'The cat sat' into three pieces and looks each one up. The lookups are 104, 324, 782: a tensor of shape (3,), every ID below 1,000. The pieces come from byte-pair encoding: merge the most frequent pair, repeat. Six merges turn 26 characters into 11 tokens. In code, one dictionary lookup; torch.tensor gives shape (3,). The space belongs to the token after it. Start free at indexaiacademy.com.
All 38 videos, by what they're for.
One prompt, “The cat sat”, through the whole model: tokens, embeddings, the attention matrix, the feed-forward layer, and the probability over the next word.
Each ID picks one row of the embedding matrix, a positional wave is added, and the result is the 3 × 8 matrix that enters the first block.
Queries, keys and values from the same rows, then the 3 × 3 matrix of weights: “ sat” reads 0.40 of its value from “ cat”.
Each row is widened from 8 numbers to 32, bent by GELU and squeezed back: 552 parameters here, 4,722,432 per layer in GPT-2.
The last row becomes a score for every token, softmax makes them probabilities, temperature reshapes them, and the chosen token joins the prompt.
Never trained an AI? Teach a small one to write, right in your browser. It takes about 20 seconds and needs no account. Teach it to write