How transformers think
One prompt, “The cat sat”, through the whole model: tokens, embeddings, the attention matrix, the feed-forward layer, and the probability over the next word.
 Index Ai Academy
Queries, keys and values from the same rows, then the 3 × 3 matrix of weights: “ sat” reads 0.40 of its value from “ cat”.
Inside a block, each row is projected three ways: query, key and value, through 8 × 4 weights. The query of 'sat' meets each key as a dot product: its score with 'cat', −0.32, is its highest. Divide by √d_k, 2 here, and softmax each row: 'sat' reads 0.40 from 'cat', 0.31 from itself, 0.29 from 'The'. Every row sums to one: that is the attention matrix. Start free at indexaiacademy.com.
All 38 videos, by what they're for.
One prompt, “The cat sat”, through the whole model: tokens, embeddings, the attention matrix, the feed-forward layer, and the probability over the next word.
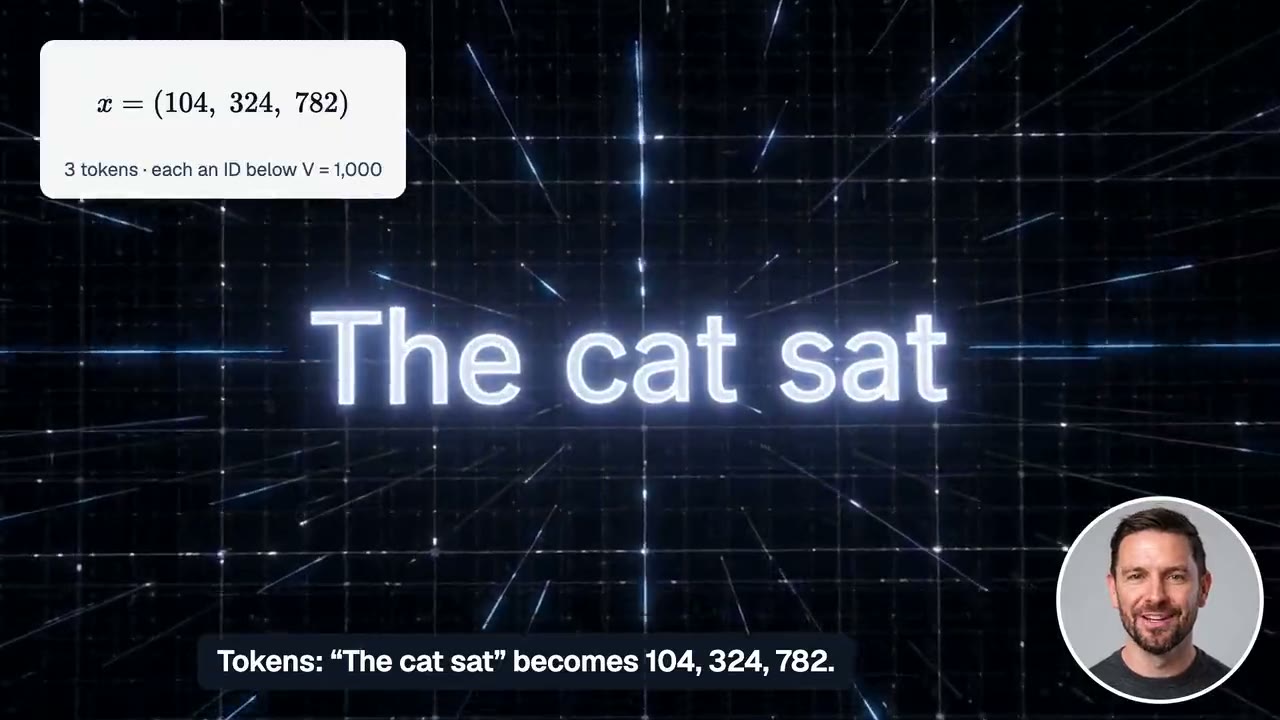
“The cat sat” is cut into three tokens and looked up as 104, 324 and 782: a tensor of shape (3,) with T = 3 and V = 1,000.
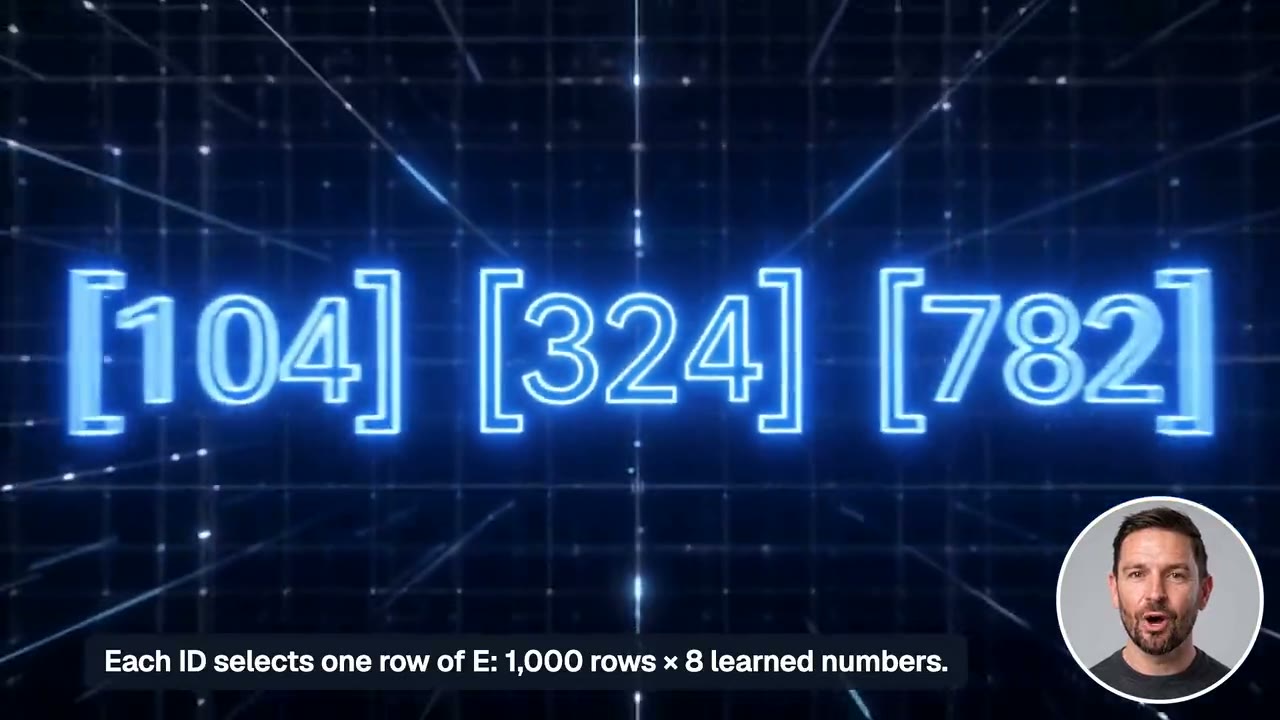
Each ID picks one row of the embedding matrix, a positional wave is added, and the result is the 3 × 8 matrix that enters the first block.
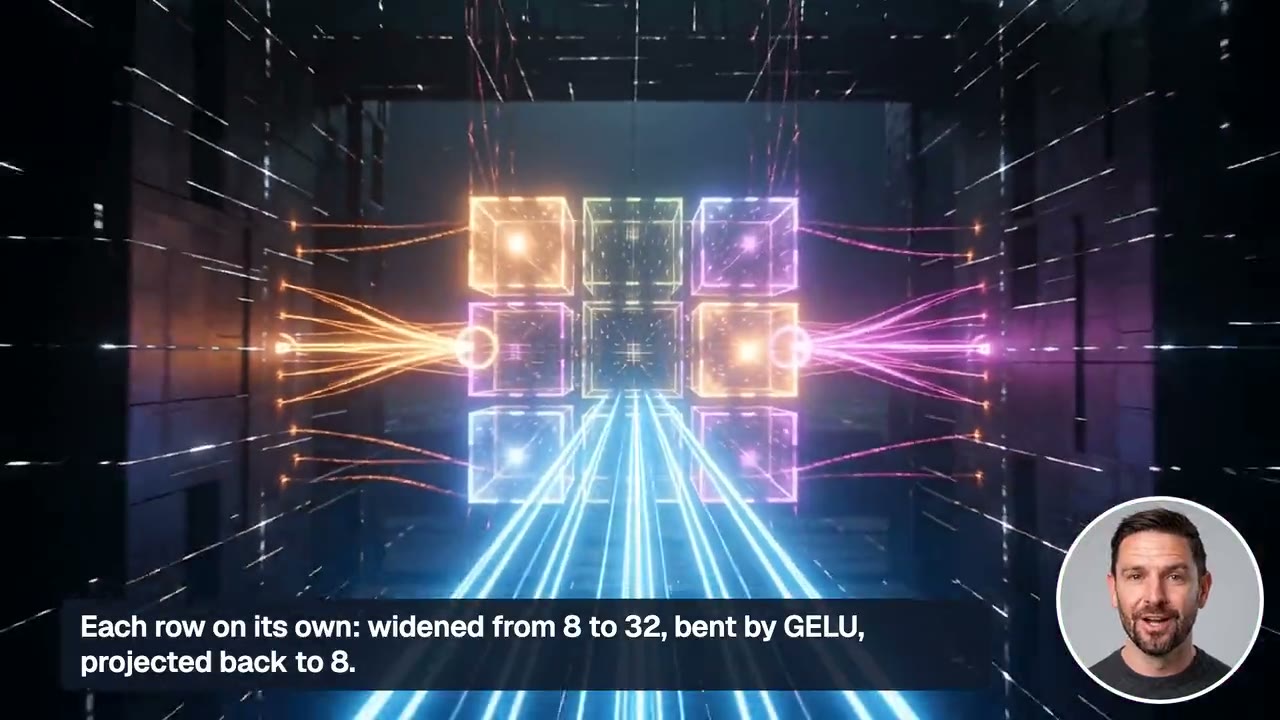
Each row is widened from 8 numbers to 32, bent by GELU and squeezed back: 552 parameters here, 4,722,432 per layer in GPT-2.
The last row becomes a score for every token, softmax makes them probabilities, temperature reshapes them, and the chosen token joins the prompt.
Never trained an AI? Teach a small one to write, right in your browser. It takes about 20 seconds and needs no account. Teach it to write